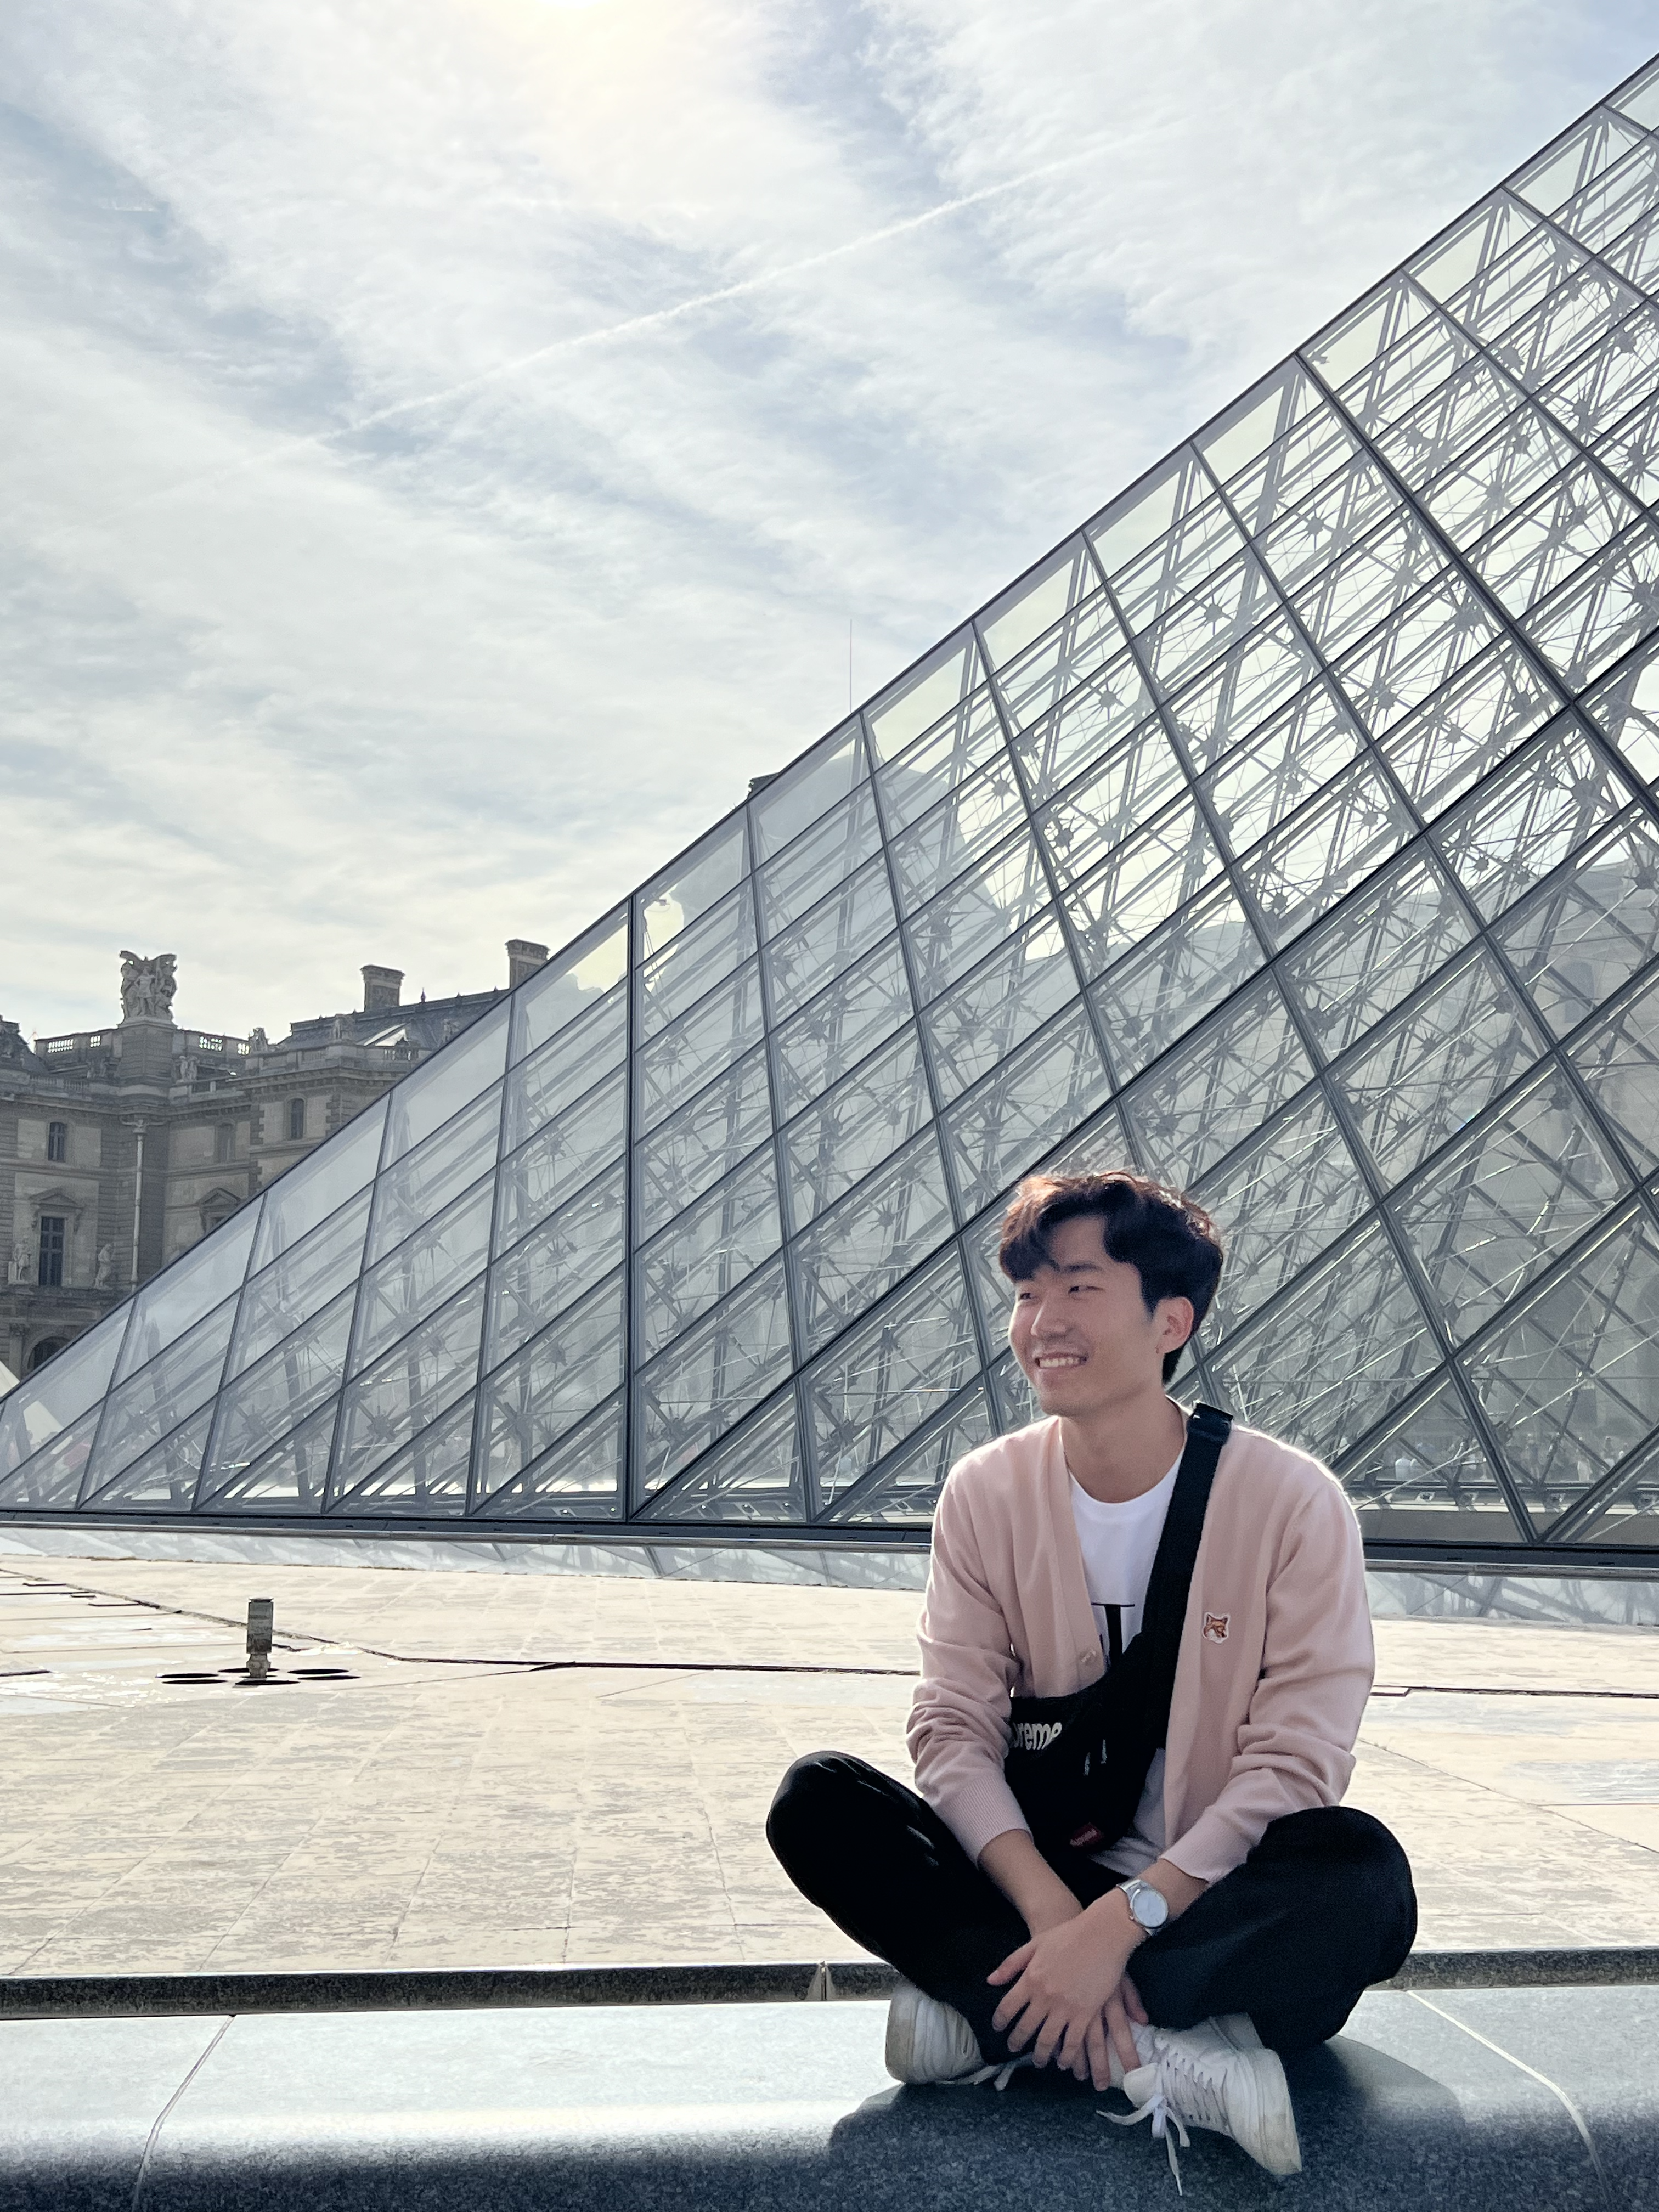
About Me
Hi, I’m Dohwan Ko, a final-year Ph.D. student at Machine Learning and Vision Lab (MLV) in Korea University, under the supervision of Prof. Hyunwoo J. Kim. I received my B.S. degree in Computer Science and Engineering in Korea University at Feb. 2021. I was fortunate to gain research experience through internships at Meta Reality Labs and NEC Labs America, where my work centered on multi-modal video understanding using large language models and foundation models. Currently, my research interest includes:
- Multi-Modal Agent AI and Reasoning
- Video Large Language Models and Foundation Models
- Efficient Multi-Modal Video Understanding
I’m looking for my next position in the industry starting in 2027. If my profile aligns with your institution’s needs, I would greatly appreciate the opportunity to connect.
Please feel free to reach out at ikodoh[AT]korea.ac.kr.
Education
Korea University Seoul, South Korea
Mar. 2021 – Feb. 2027 (expected)M.S. & Ph.D. in Computer Science and Engineering
Korea University Seoul, South Korea
Mar. 2017 – Feb. 2021B.S. in Computer Science and Engineering
Work Experiences

Meta Menlo Park, CA, USA
April 2026 – Jul. 2026Research Scientist Intern, Meta Reality Labs
Meta Menlo Park, CA, USA
Mar. 2025 – Jun. 2025Research Scientist Intern, Meta Reality Labs

NEC Labs America San Jose, CA, USA
Jun. 2024 – Aug. 2024Research Scientist Intern, Media Analytics Team

NAVER Seongnam, South Korea
Jul. 2020 – Aug. 2020Intern, User Feedback Platform
News
Aug. 2026 Our paper SVMemAgent: A Streaming Video Memory Agent for Query-Agnostic Online Frame Selection has been accepted to the Wearable AI Workshop at ECCV 2026!
Jul. 2026 Our paper VideoSearch-R1: Iterative Video Retrieval and Reasoning via Soft Query Refinement has been accepted to ECCV 2026!
Feb. 2026 Two papers, MoE-GRPO and DocPrune, have been accepted to CVPR 2026!
Jun. 2025 Our paper Bidirectional Likelihood Estimation with Multi-Modal Large Language Models for Text-Video Retrieval (BLiM) has been accepted to ICCV 2025 as a Highlight! (top 9.7%)
Sep. 2024 Our paper LLaMo: Large Language Model-based Molecular Graph Assistant has been accepted to NeurIPS 2024!
Oct. 2023 Our paper Large Language Models are Temporal and Causal Reasoners for Video Question Answering (Flipped-VQA) has been accepted to EMNLP 2023!
Jul. 2023 Our paper Open-vocabulary Video Question Answering (OVQA) has been accepted to ICCV 2023!
Feb. 2023 Our paper Meta Loss Transformer (MELTR) has been accepted to CVPR 2023!
Nov. 2022 Our paper Randomly Shuffled Convolution for Self-Supervised Representation Learning (Croffle) has been accepted to Information Sciences!
Mar. 2022 Our paper Video-Text Representation Learning via Differentiable Weak Alignment (VT-TWINS) has been accepted to CVPR 2022!
Oct. 2021 Our paper Search-and-Attack: Temporally Sparse Adversarial Perturbations on Videos has been accepted to IEEE Access!