Publications
International Conference Publications
denotes equal contribution.

VideoSearch-R1: Iterative Video Retrieval and Reasoning via Soft Query Refinement
ECCV 2026
@inproceedings{lee2026videosearchr1,
  title={VideoSearch-R1: Iterative Video Retrieval and Reasoning via Soft Query Refinement},
  author={Lee, Seohyun and Choi, Seoung and Ko, Dohwan and Kim, Jongha and Kim, Hyunwoo J.},
  booktitle={ECCV},
  year={2026}
}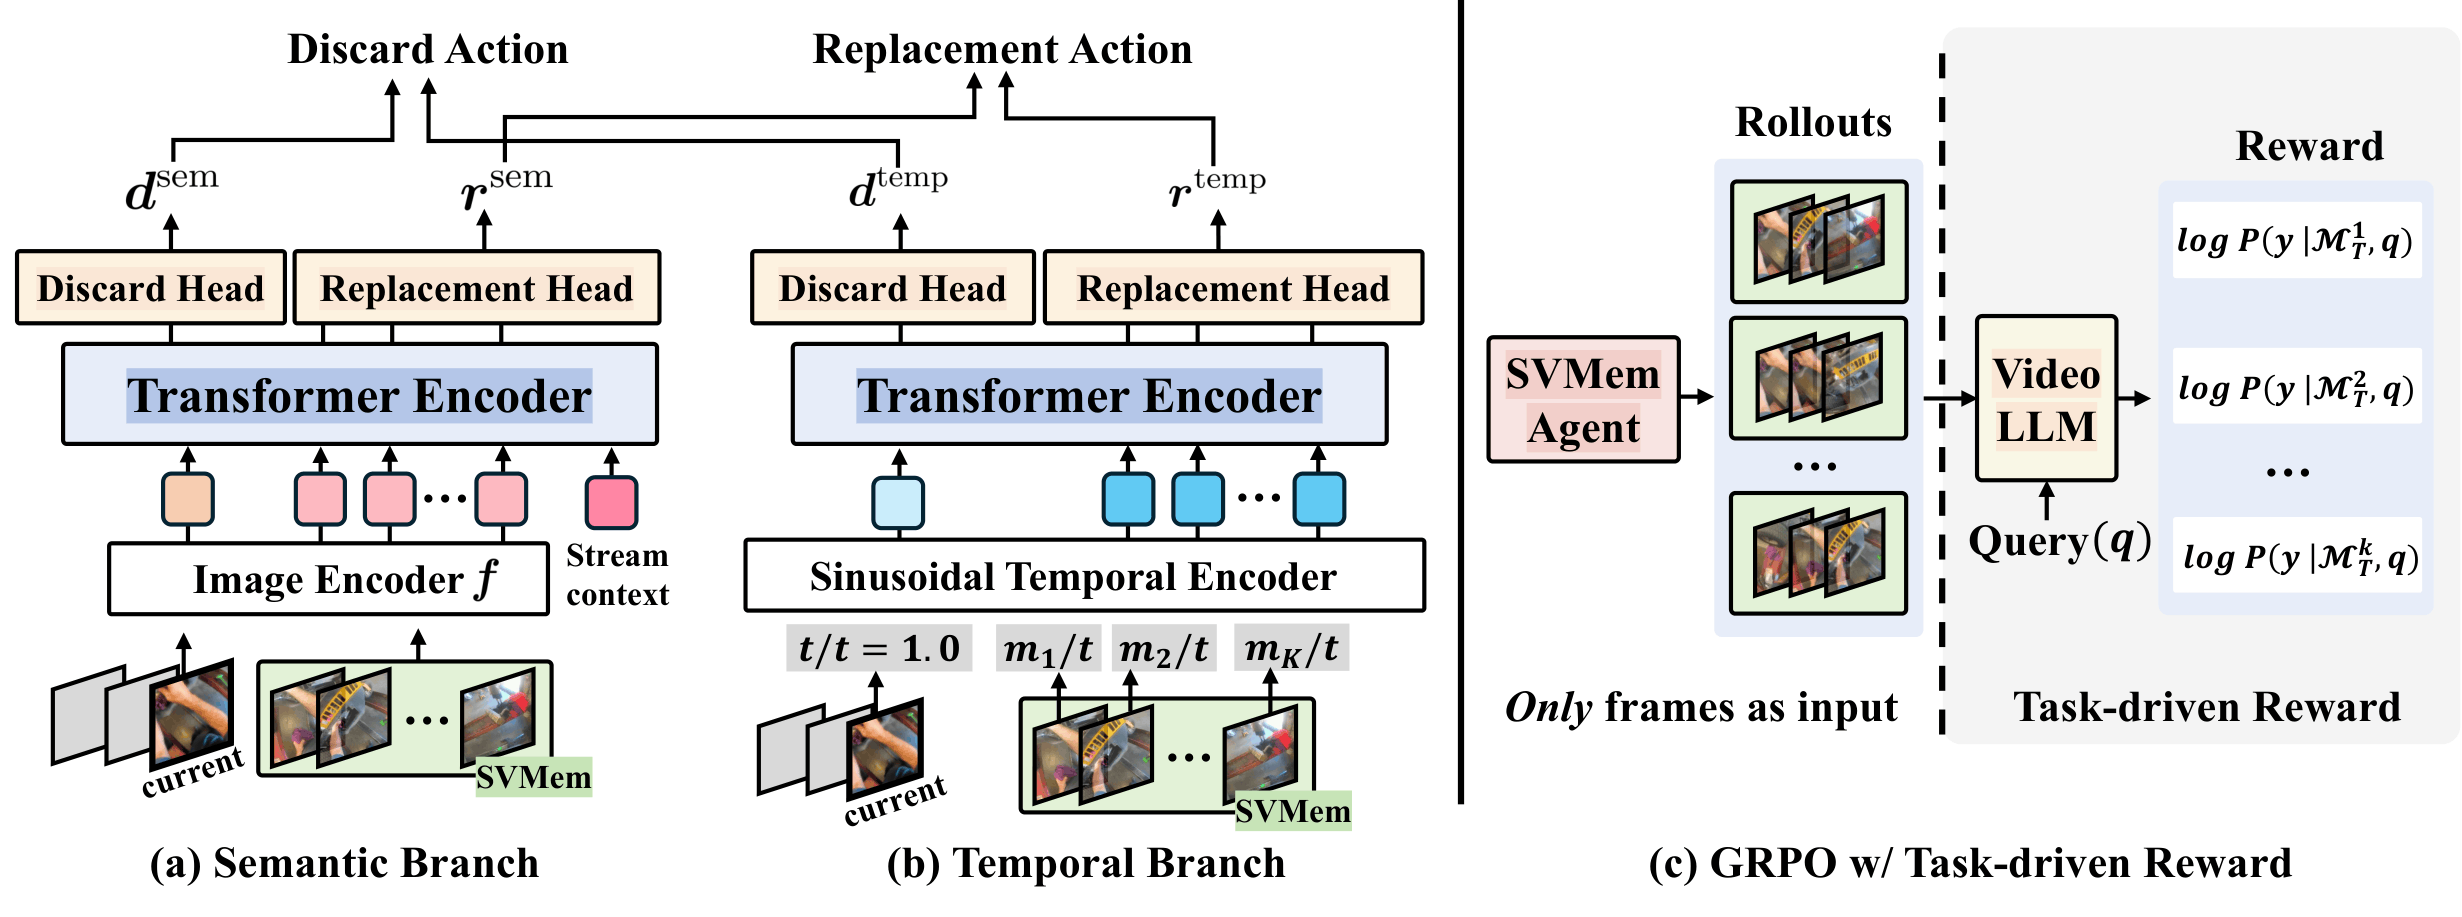
SVMemAgent: A Streaming Video Memory Agent for Query-Agnostic Online Frame Selection
ECCVW 2026 Wearable AI Workshop
@inproceedings{ko2026svmemagent,
  title={SVMemAgent: A Streaming Video Memory Agent for Query-Agnostic Online Frame Selection},
  author={Ko, Dohwan and Lee, Ji Soo and Chuang, Pierce and Chatterjee, Debojeet and Shenoy, Ashish and Lu, Yichao and Moon, Shane and Dong, Luna and Bhardwaj, Vikas and Kim, Hyunwoo J.},
  booktitle={ECCVW},
  year={2026}
}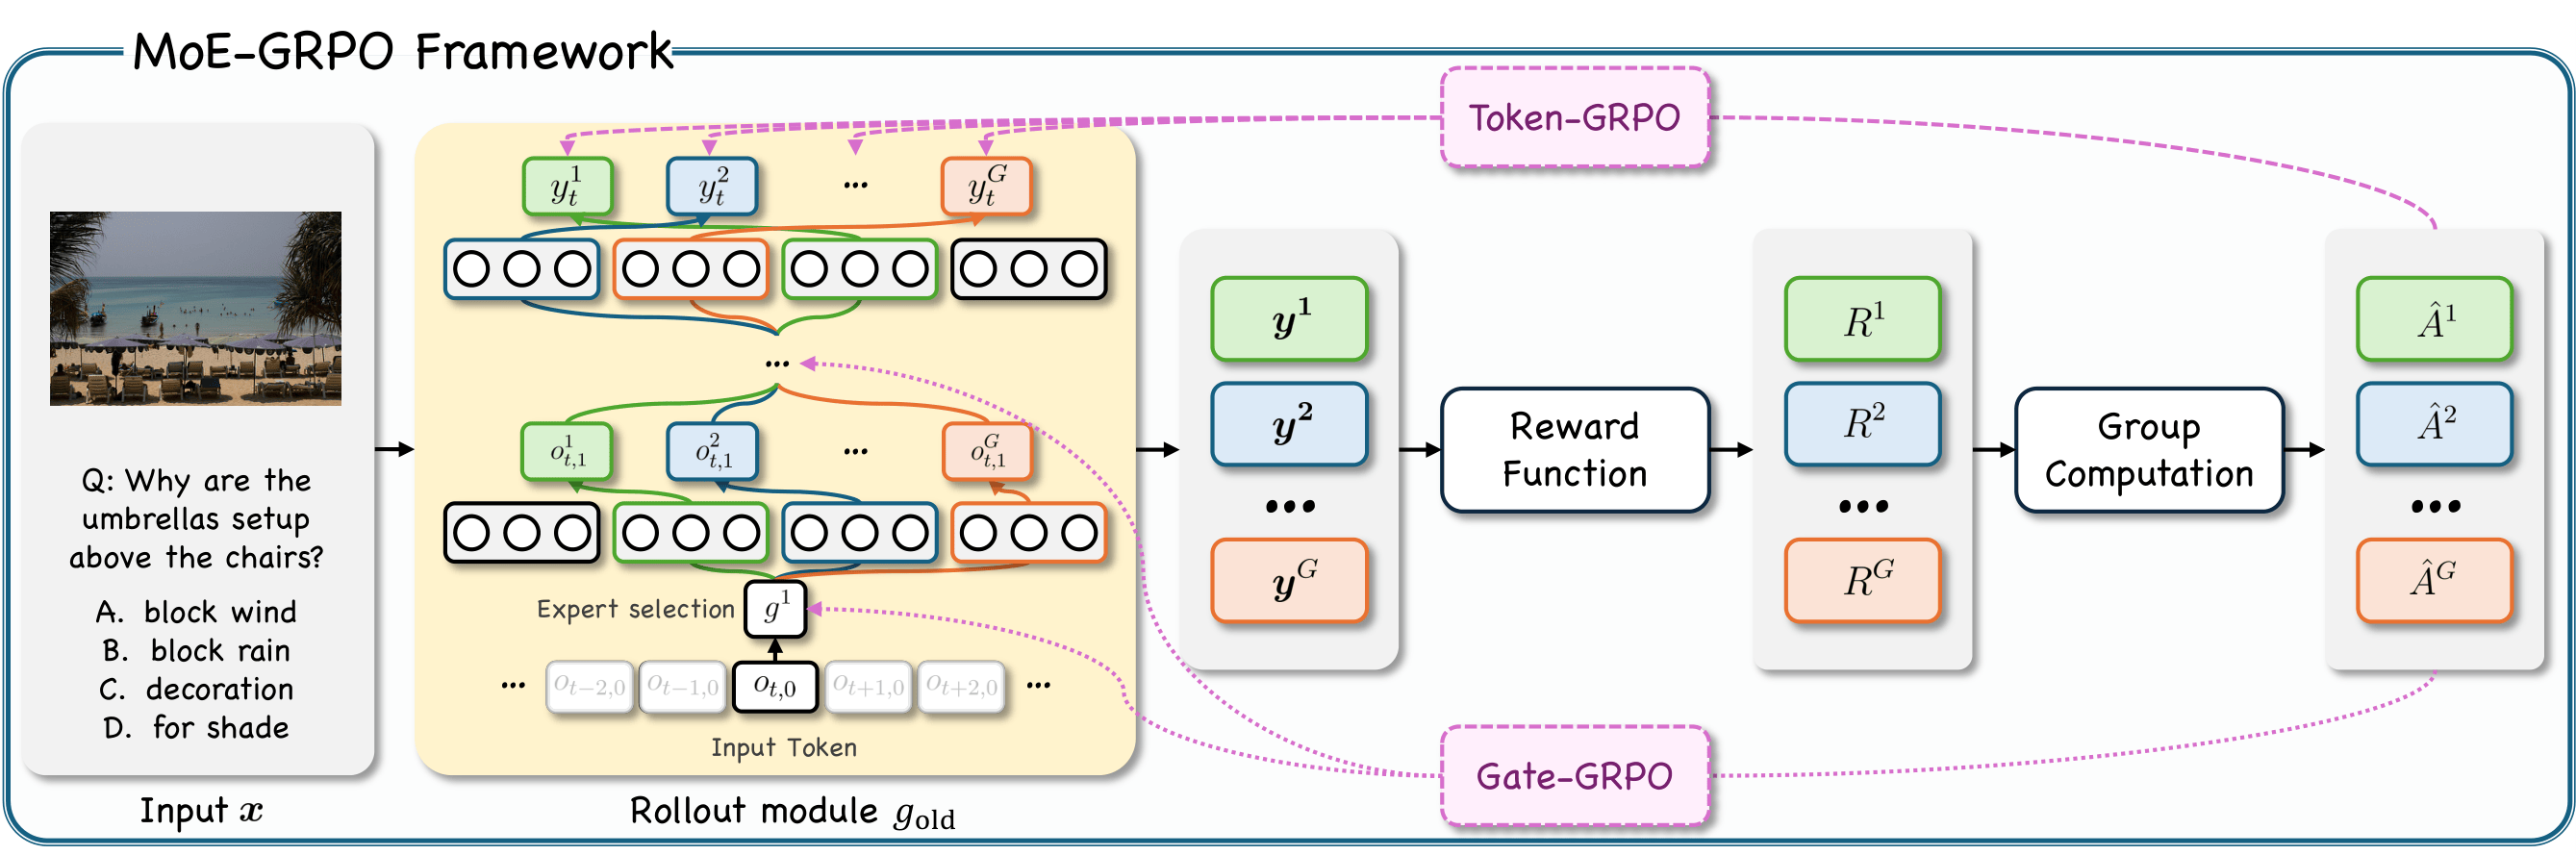
MoE-GRPO: Optimizing Mixture-of-Experts via Reinforcement Learning in Vision-Language Models
CVPR 2026
@inproceedings{ko2026moe,
  title={MoE-GRPO: Optimizing Mixture-of-Experts via Reinforcement Learning in Vision-Language Models},
  author={Ko, Dohwan and Park, Jinyoung and Choi, Seoung and Lee, Sanghyeok and Lee, Seohyun and Kim, Hyunwoo J},
  booktitle={CVPR},
  year={2026}
}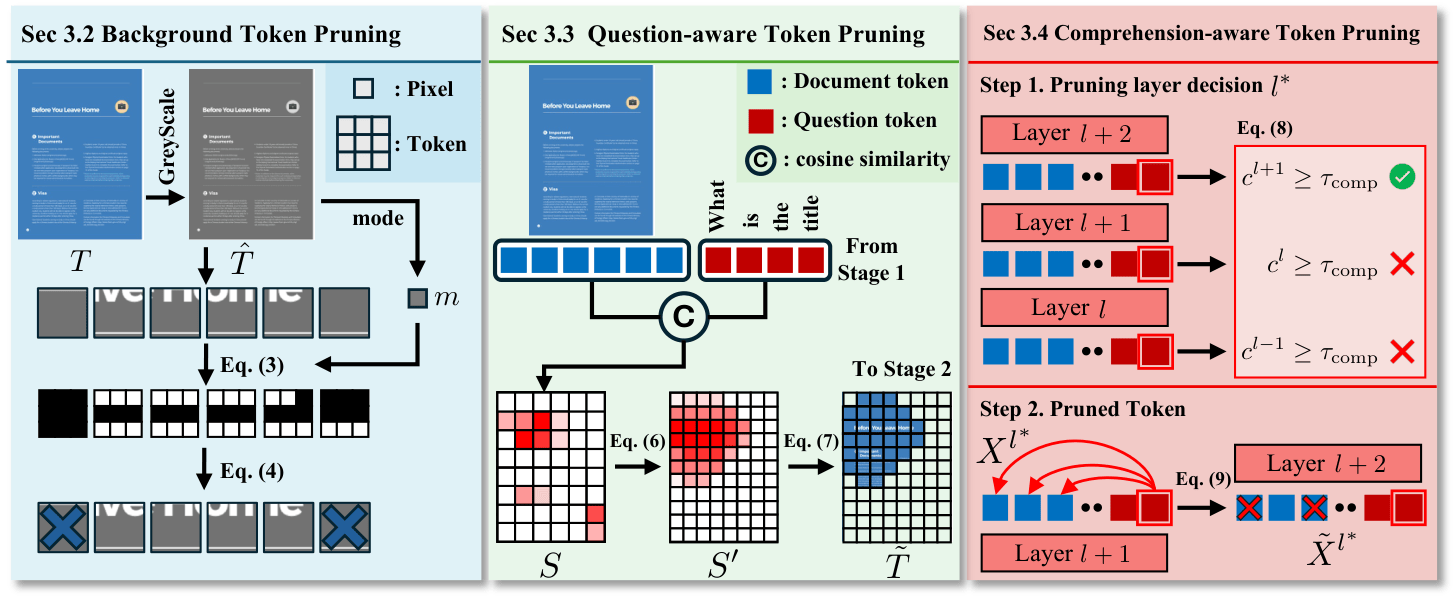
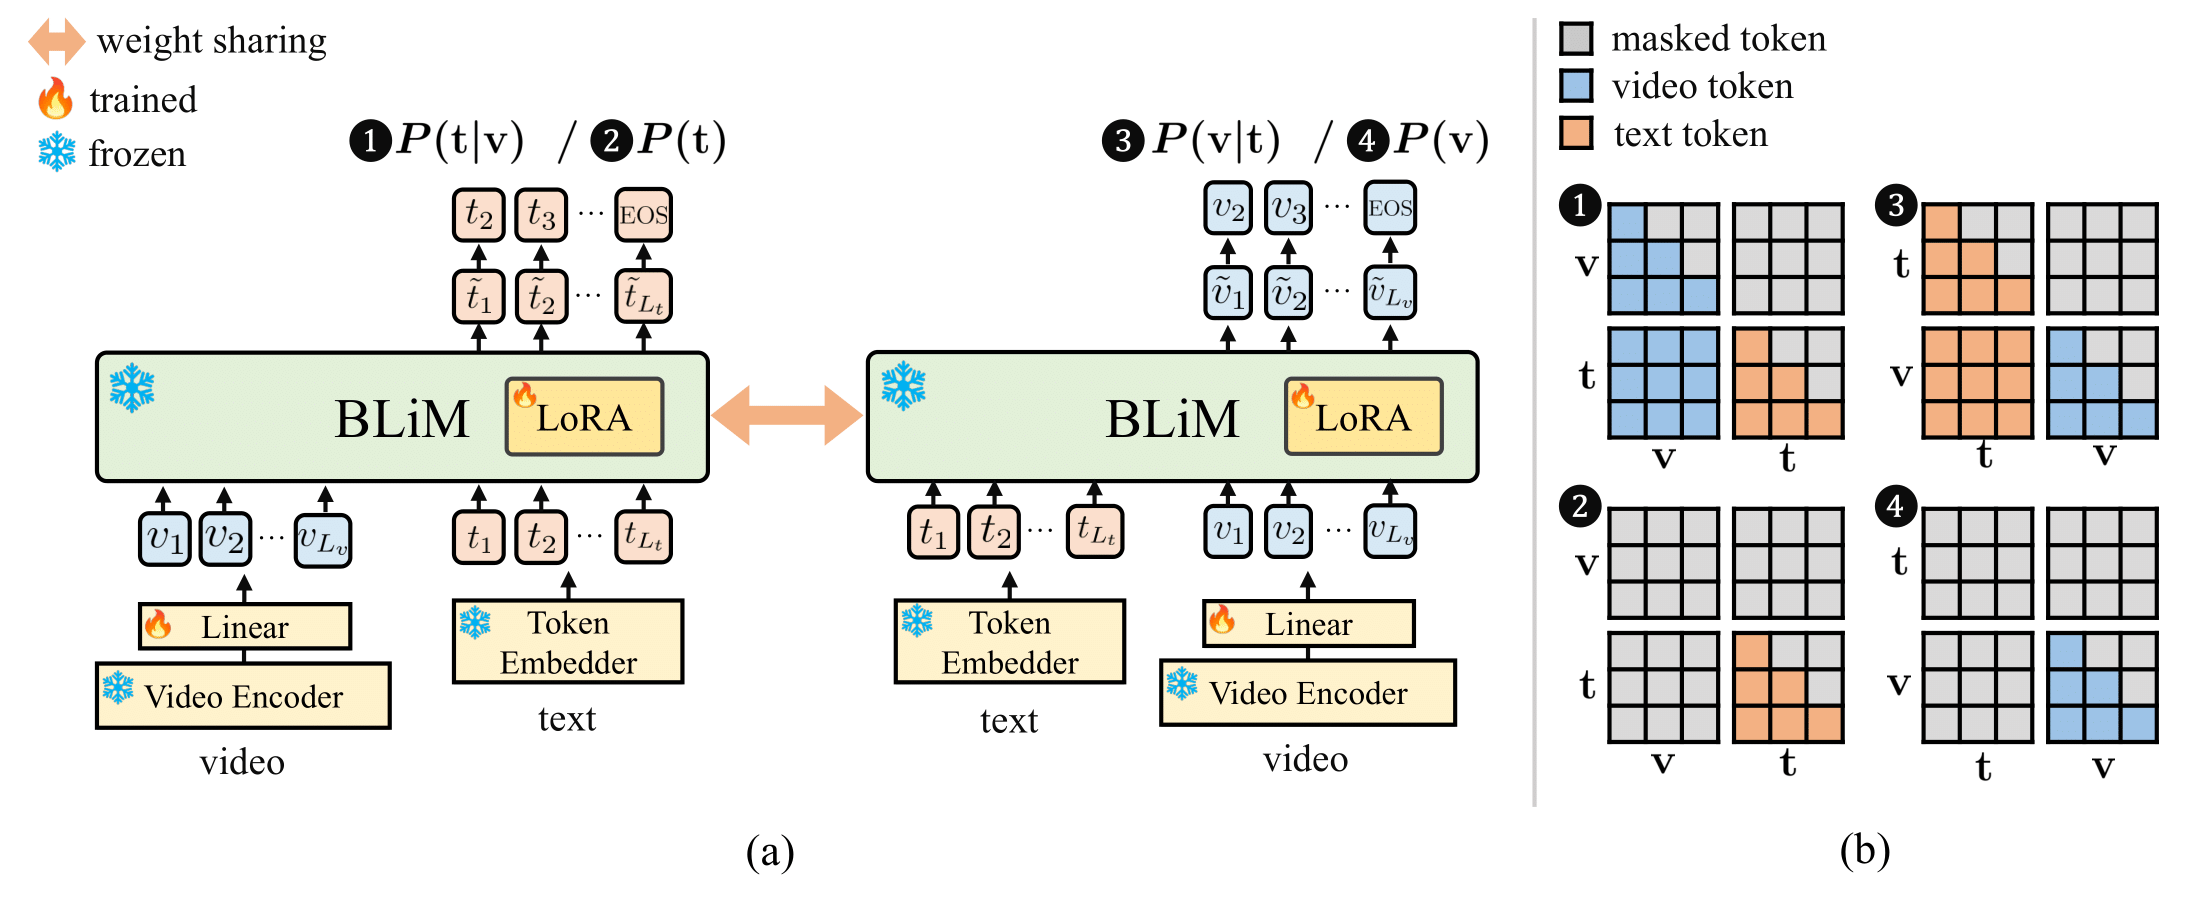
DocPrune: Efficient Document Question Answering via Background, Question, and Comprehension-aware Token Pruning
CVPR 2026
@inproceedings{choi2026docprune,
  title={DocPrune: Efficient Document Question Answering via Background, Question, and Comprehension-aware Token Pruning},
  author={Choi, Joonmyung and Lee, Sanghyeok and Kim, Jongha and Kim, Sehyung and Ko, Dohwan and Kil, Jihyung and Kim, Hyunwoo J},
  booktitle={CVPR},
  year={2026}
}
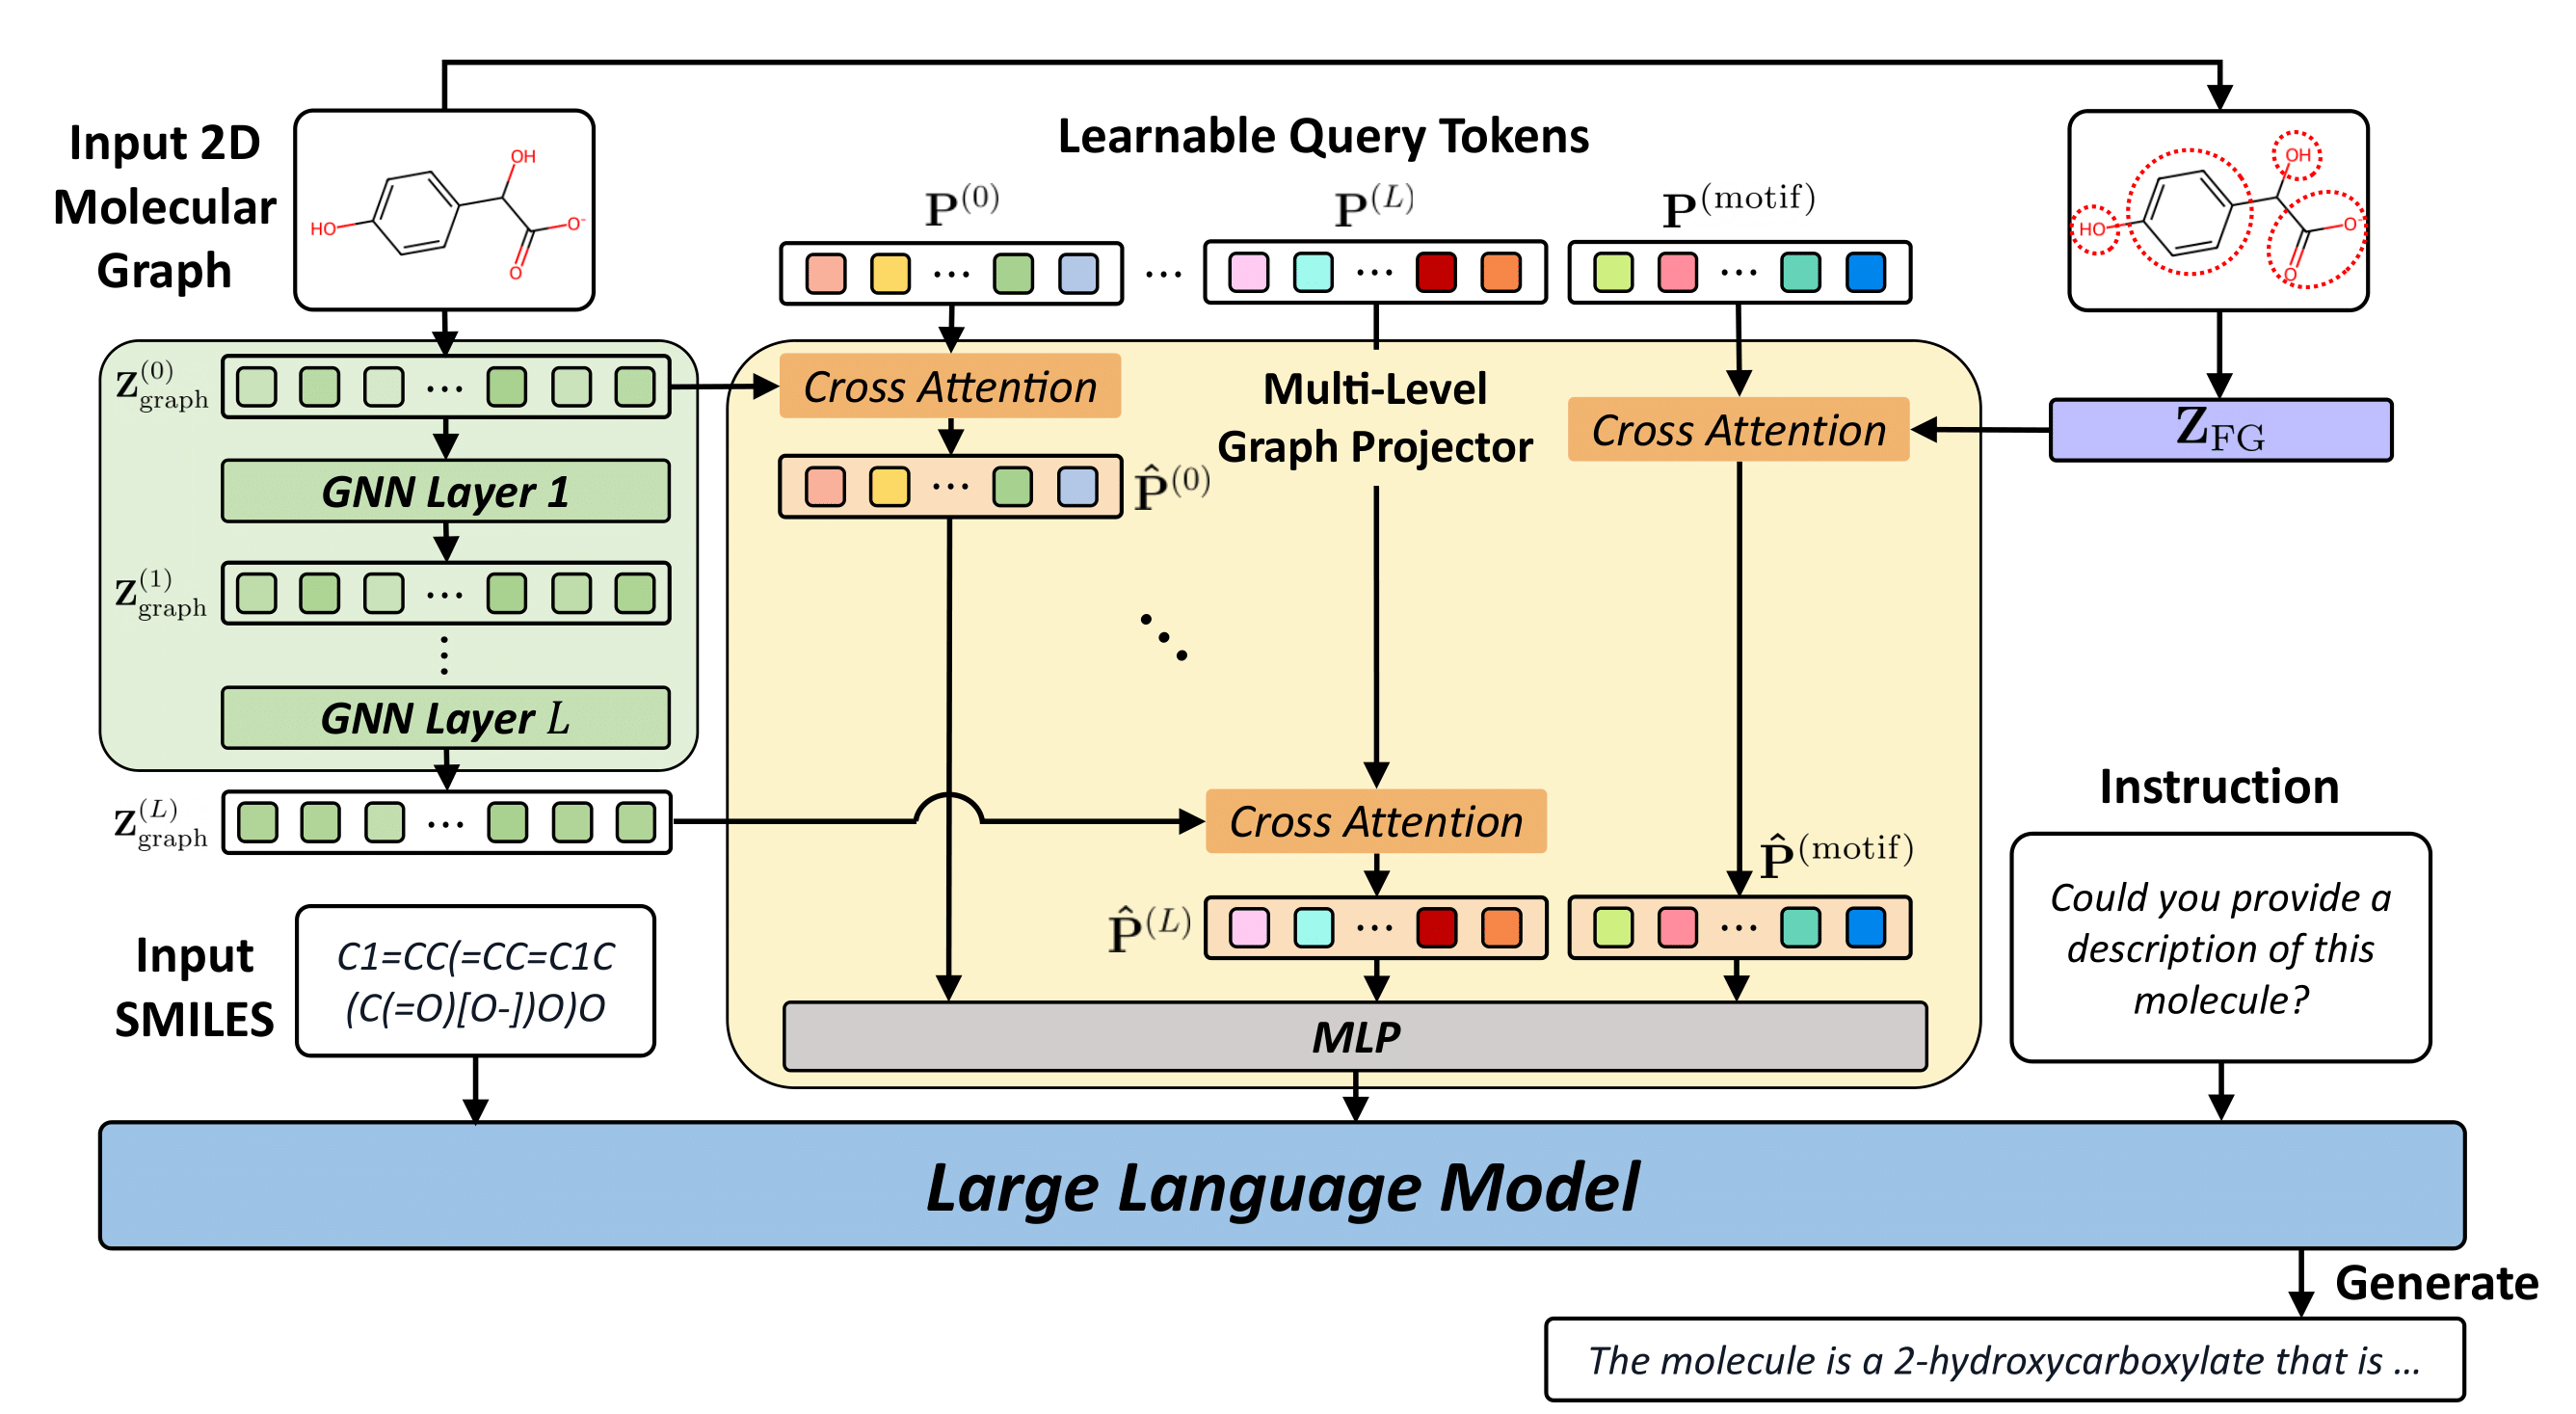
Bidirectional Likelihood Estimation with Multi-Modal Large Language Models for Text-Video Retrieval
ICCV 2025 Highlight · top 9.7%
@inproceedings{ko2025bidirectional,
  title={Bidirectional Likelihood Estimation with Multi-Modal Large Language Models for Text-Video Retrieval},
  author={Ko, Dohwan and Lee, Ji Soo and Choi, Minhyuk and Meng, Zihang and Kim, Hyunwoo J},
  booktitle={ICCV},
  year={2025}
}
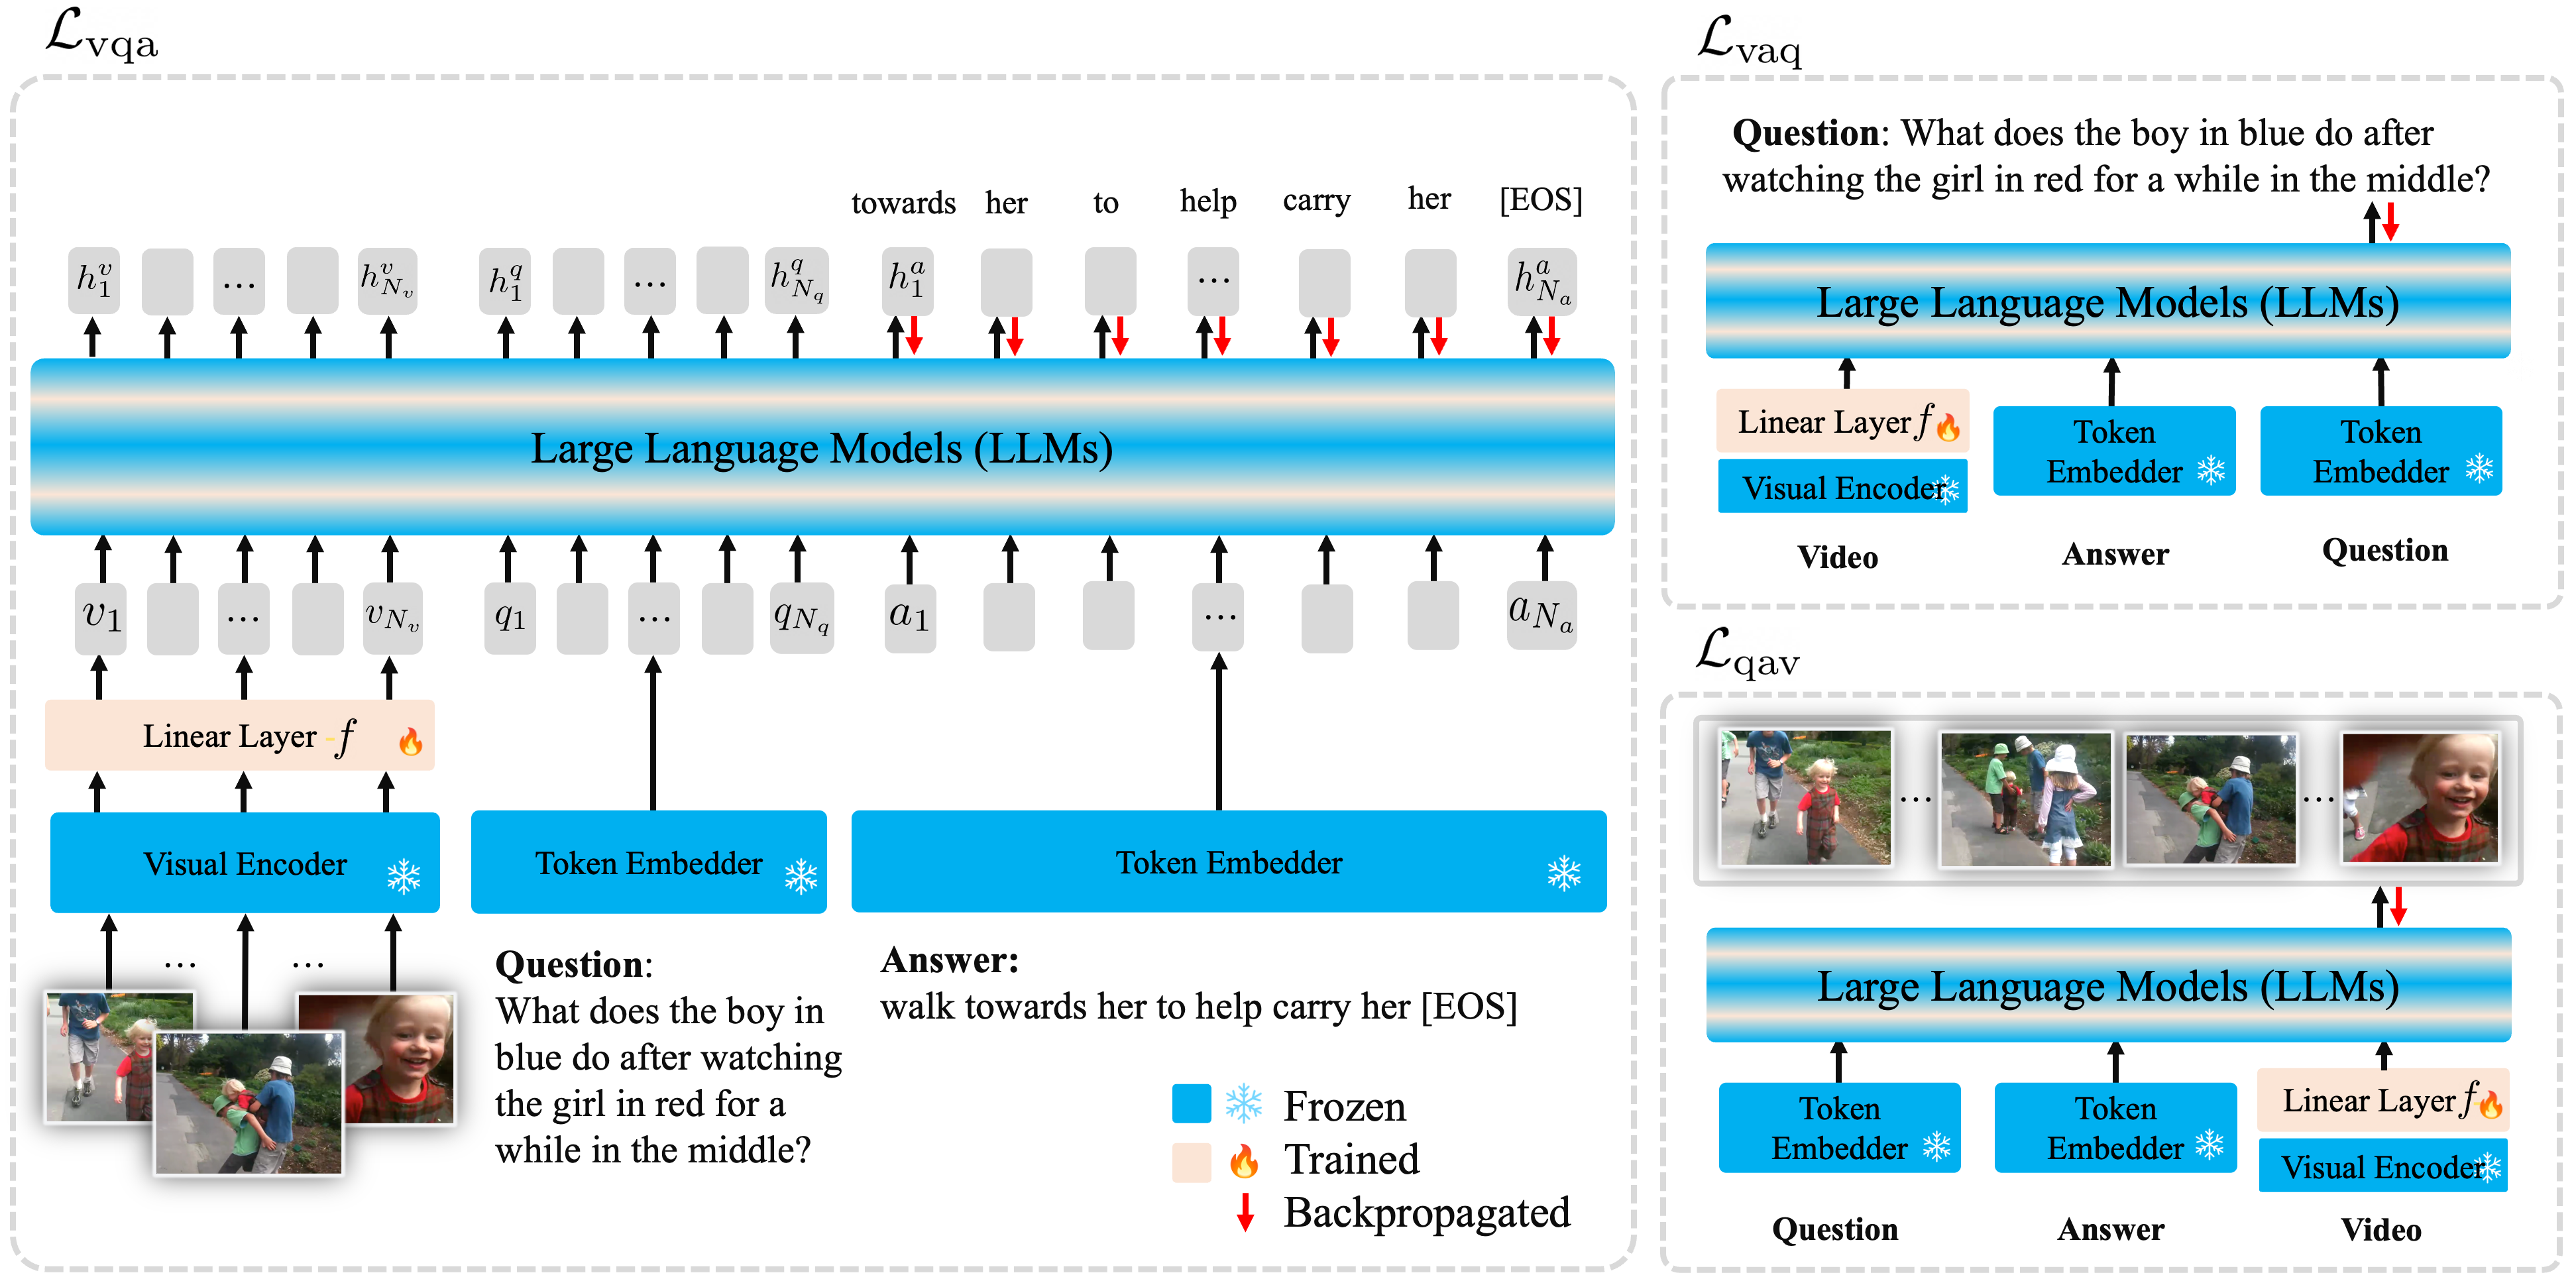
Large Language Models are Temporal and Causal Reasoners for Video Question Answering
EMNLP 2023 Main
@inproceedings{ko2023large,
  title={Large Language Models are Temporal and Causal Reasoners for Video Question Answering},
  author={Dohwan Ko and Ji Soo Lee and Wooyoung Kang and Byungseok Roh and Hyunwoo J. Kim},
  booktitle={EMNLP},
  year={2023}
}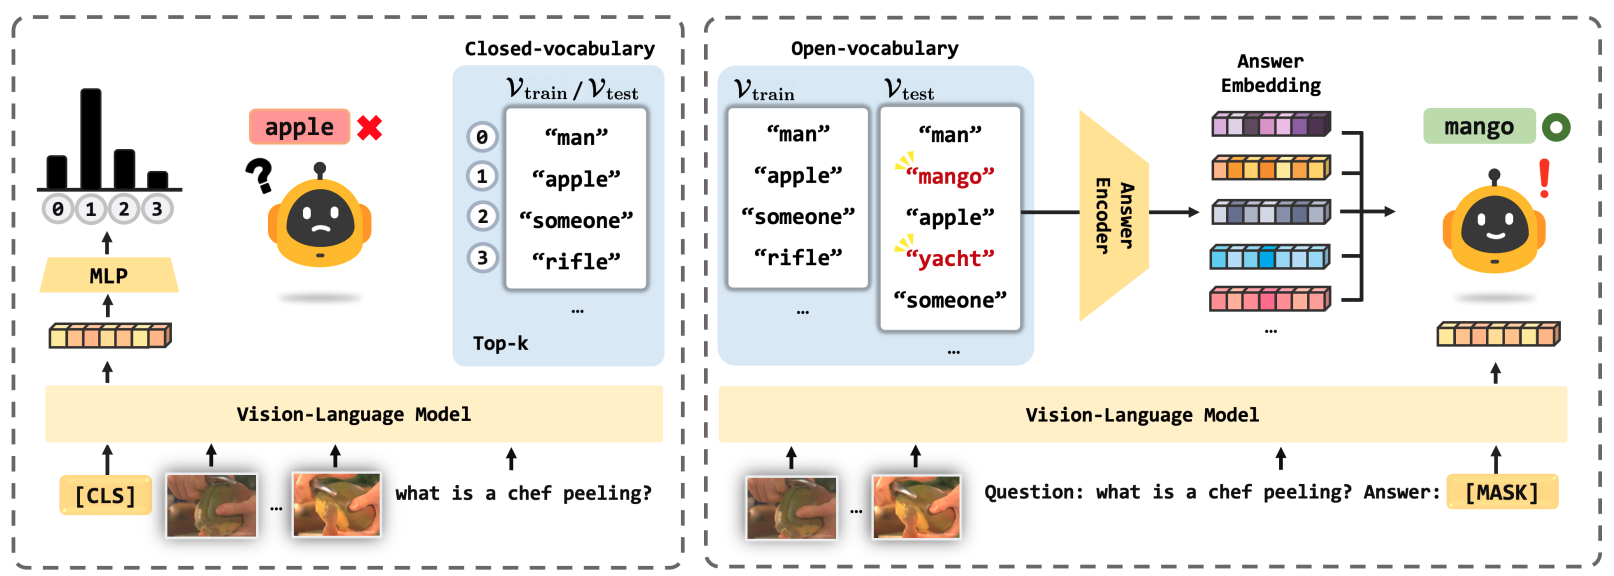
Open-Vocabulary Video Question Answering: A New Benchmark for Evaluating the Generalizability of Video Question Answering Models
ICCV 2023
@inproceedings{ko2023open,
  title={Open-vocabulary Video Question Answering: A New Benchmark for Evaluating the Generalizability of Video Question Answering Models},
  author={Ko, Dohwan and Lee, Ji Soo and Choi, Miso and Chu, Jaewon and Park, Jihwan and Kim, Hyunwoo J},
  booktitle={ICCV},
  year={2023}
}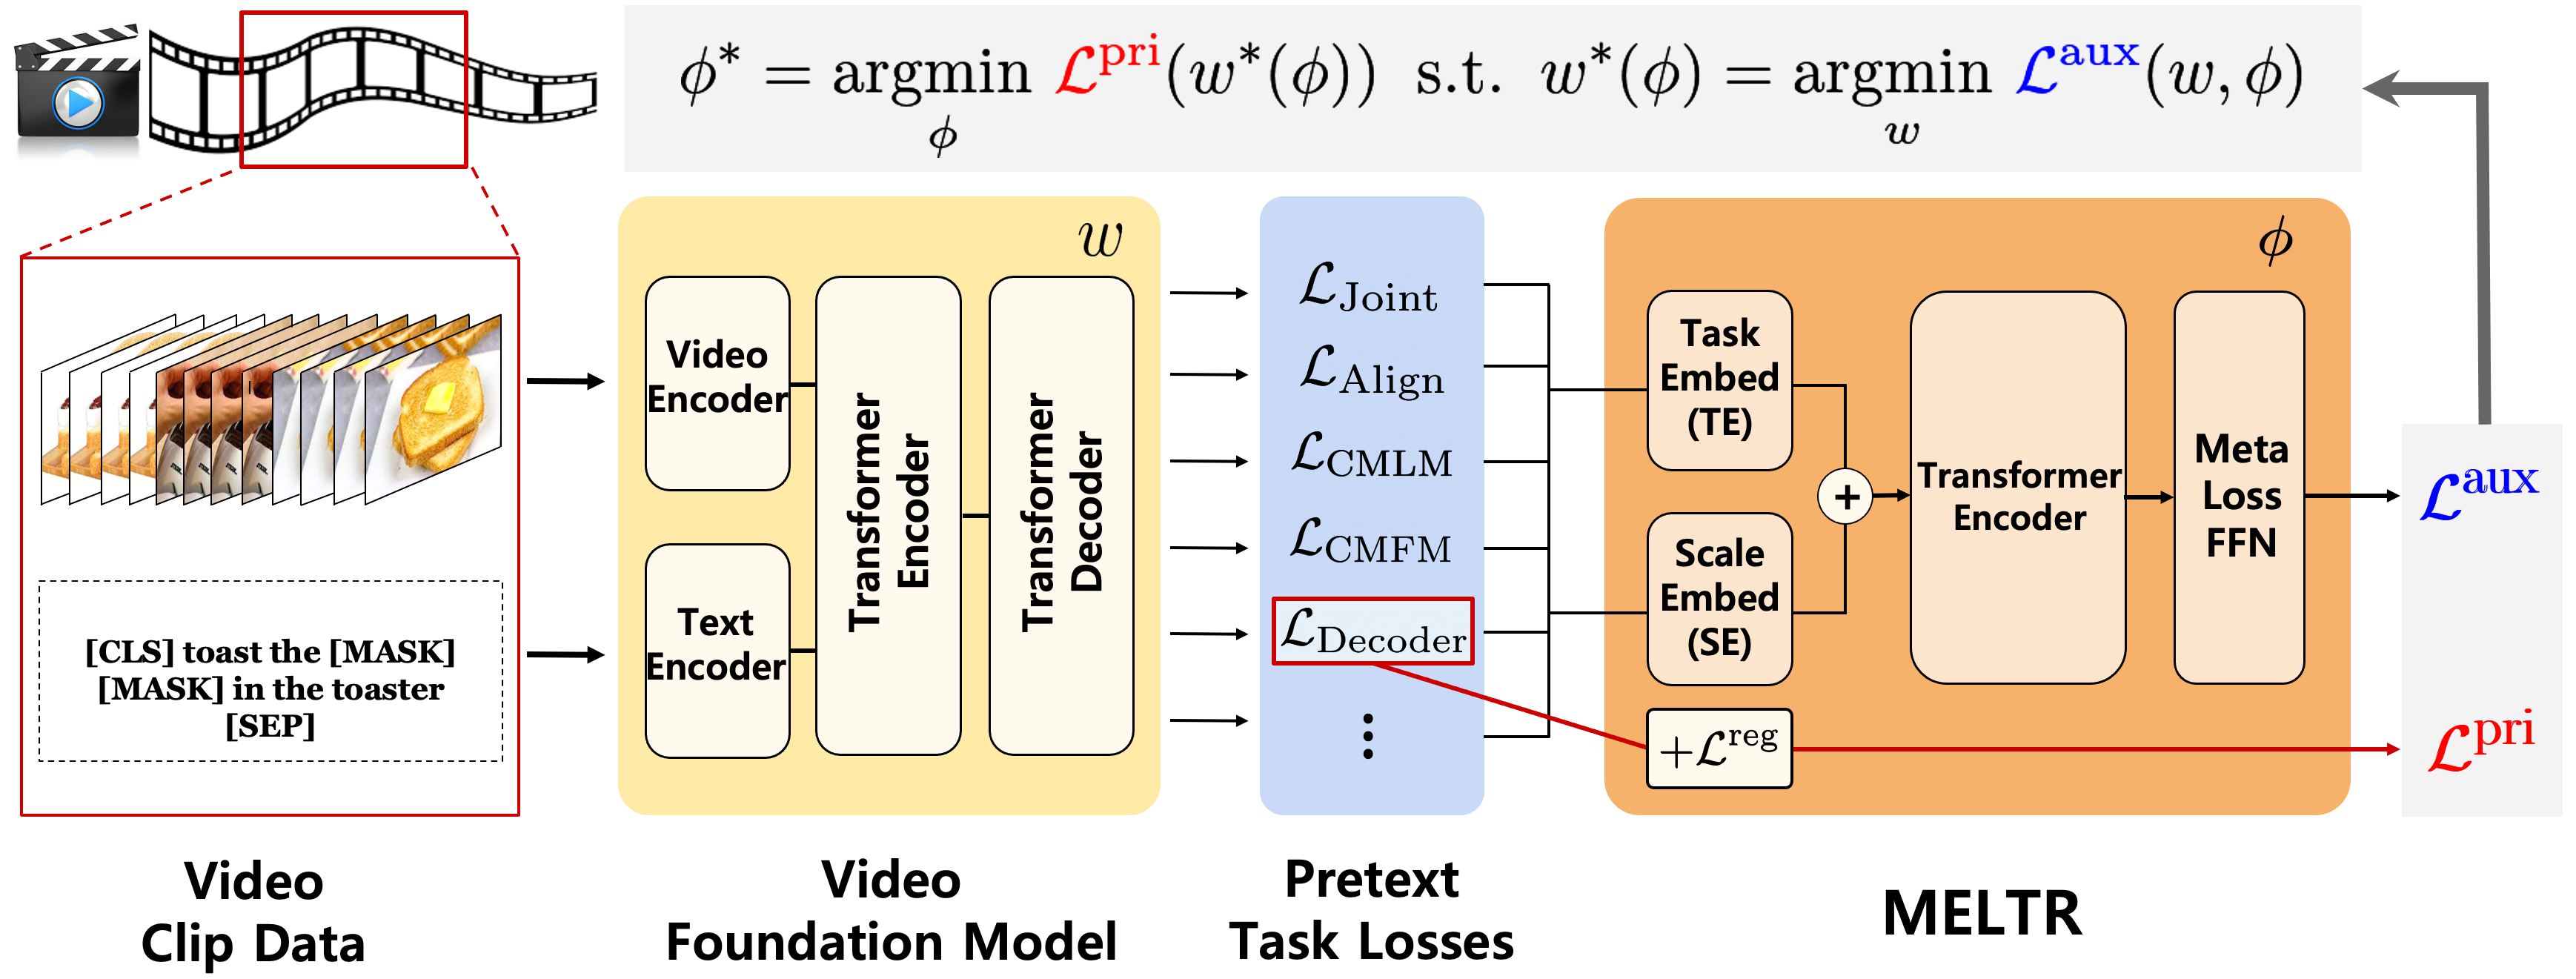
MELTR: Meta Loss Transformer for Learning to Fine-tune Video Foundation Models
CVPR 2023
@inproceedings{ko2023melrt,
  title={MELTR: Meta Loss Transformer for Learning to Fine-tune Video Foundation Models},
  author={Ko, Dohwan and Choi, Joonmyung and Choi, Hyeong Kyu and On, Kyoung-Woon and Roh, Byungseok and Kim, Hyunwoo J},
  booktitle={CVPR},
  year={2023}
}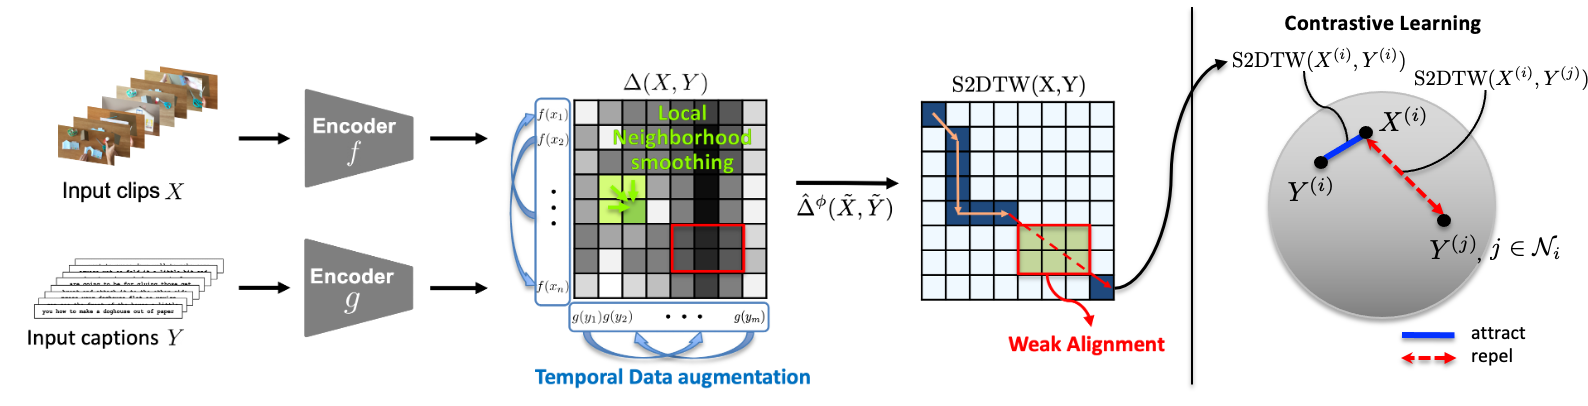
Video-Text Representation Learning via Differentiable Weak Temporal Alignment
CVPR 2022
@inproceedings{ko2022video,
  title={Video-Text Representation Learning via Differentiable Weak Temporal Alignment},
  author={Ko, Dohwan and Choi, Joonmyung and Ko, Juyeon and Noh, Shinyeong and On, Kyoung-Woon and Kim, Eun-Sol and Kim, Hyunwoo J},
  booktitle={CVPR},
  year={2022}
}International Journal Publications
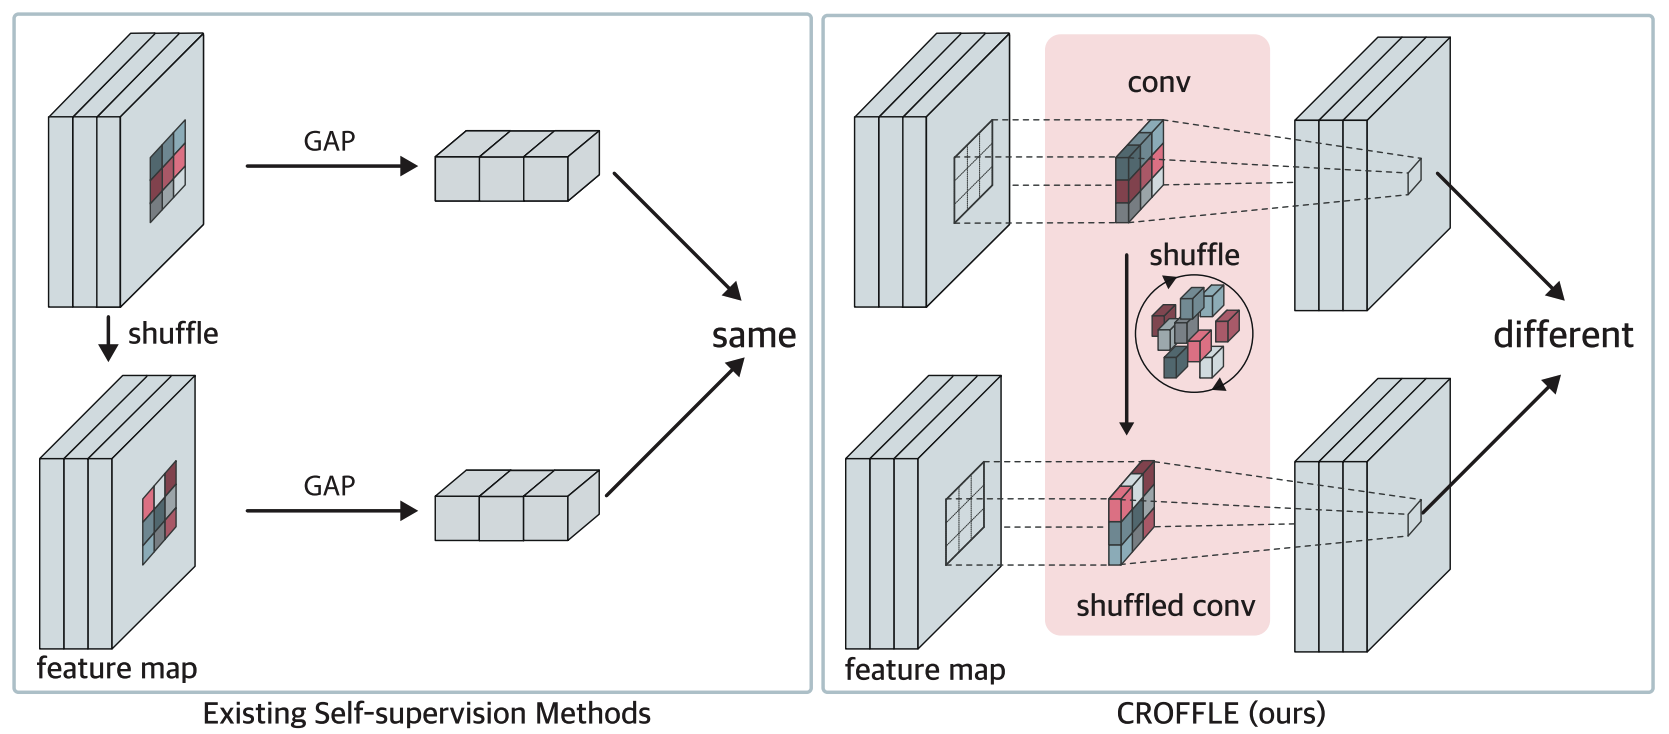
Randomly Shuffled Convolution for Self-Supervised Representation Learning
Information Sciences 2023
@article{oh2023randomly,
  title={Randomly shuffled convolution for self-supervised representation learning},
  author={Oh, Youngjin and Jeon, Minkyu and Ko, Dohwan and Kim, Hyunwoo J},
  journal={Information Sciences},
  year={2023}
}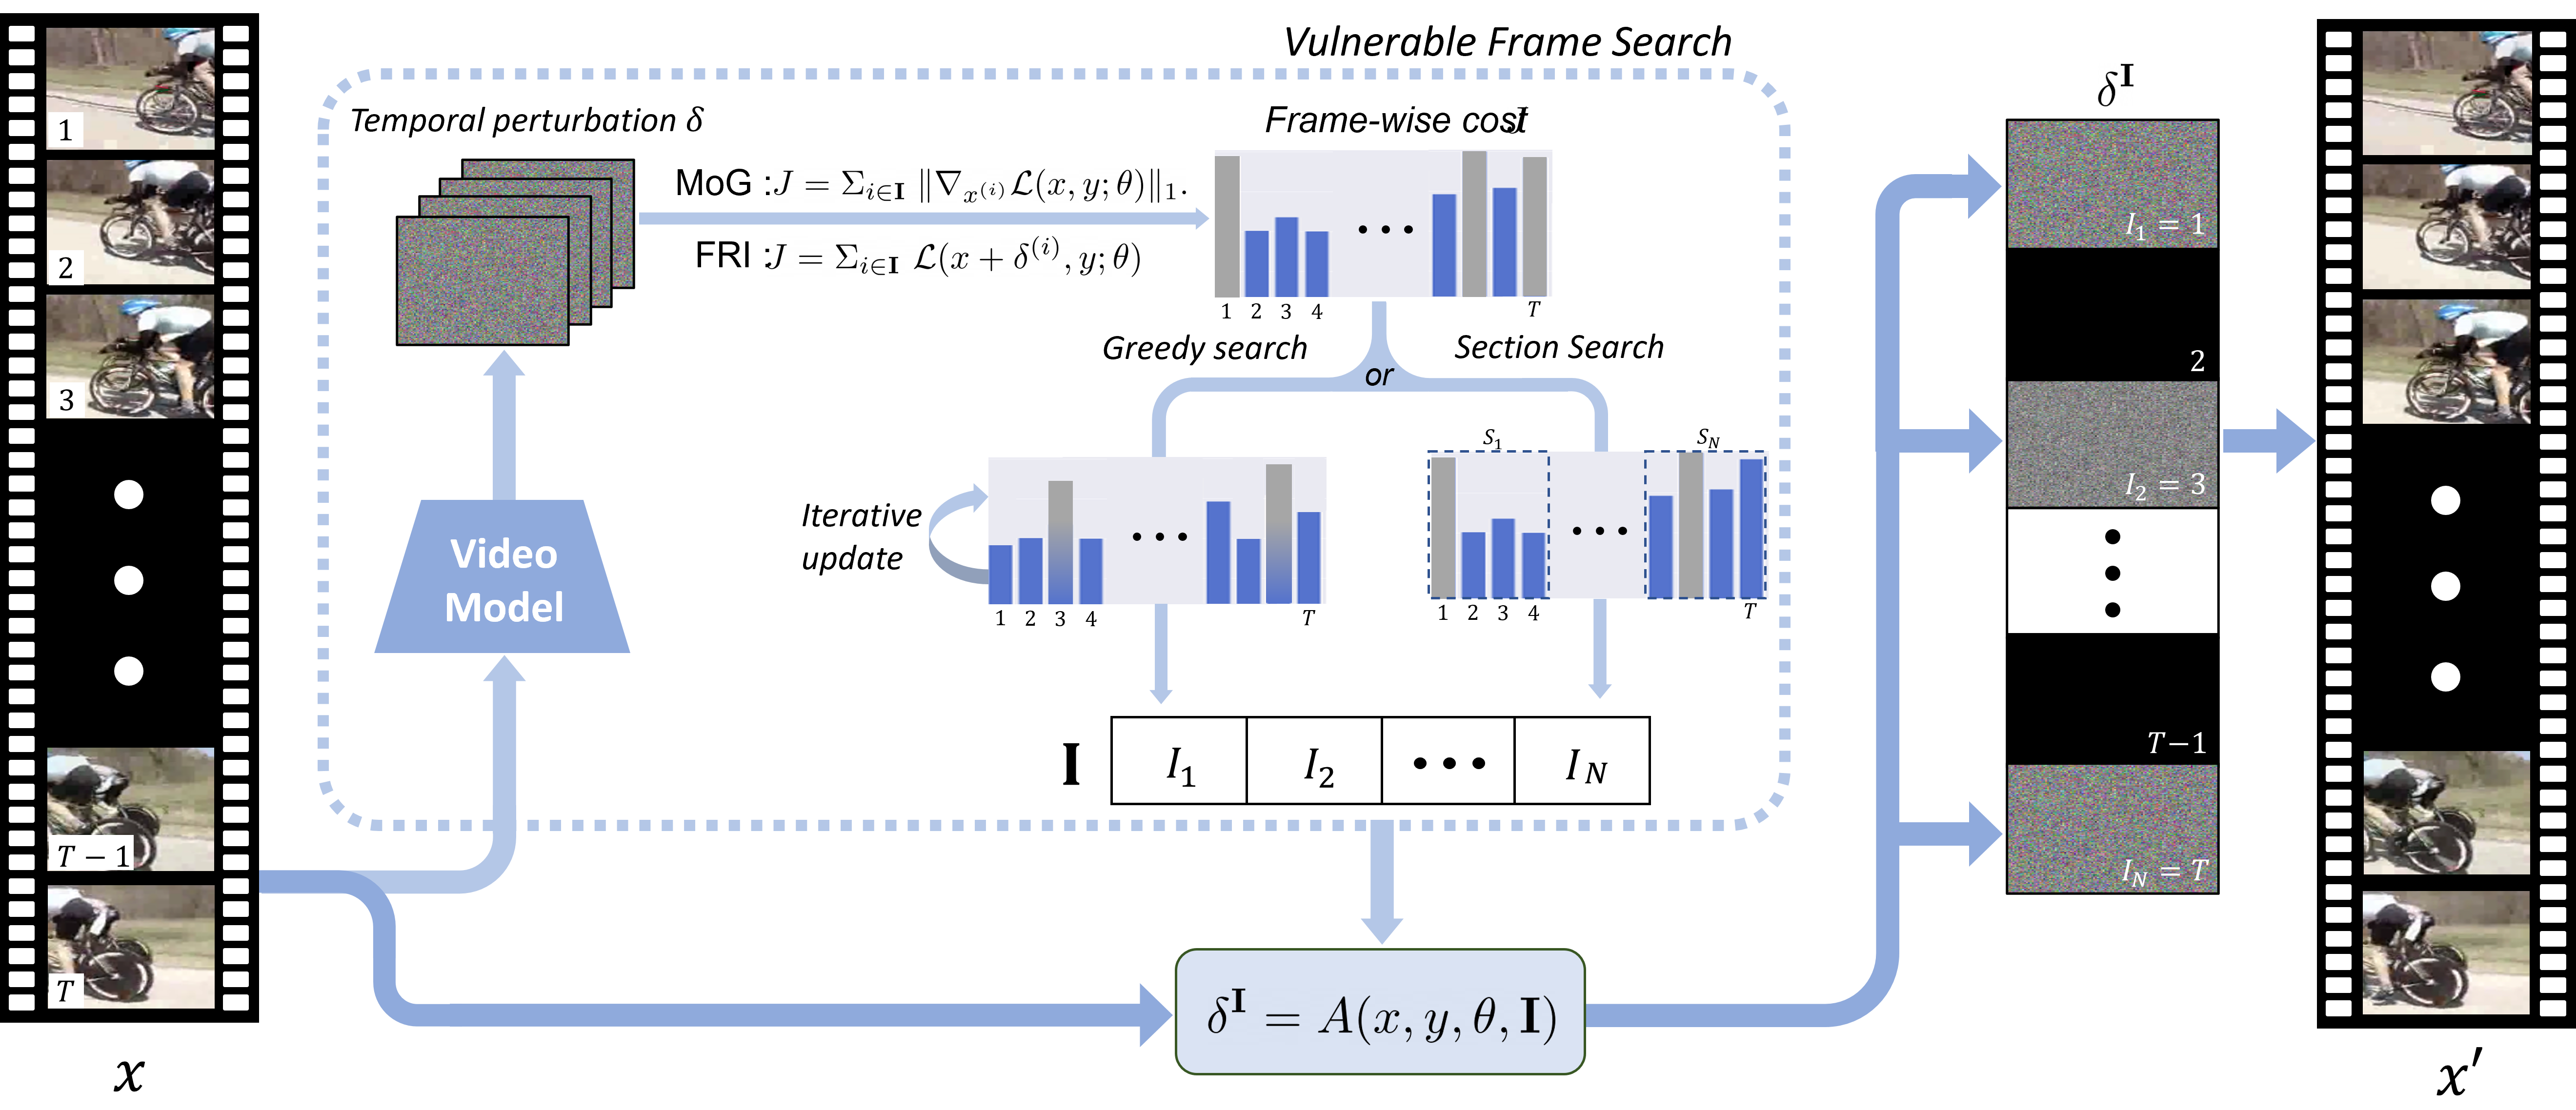
Search-and-Attack: Temporally Sparse Adversarial Perturbations on Videos
IEEE Access 2021
@article{heo2021search,
  title={Search-and-attack: temporally sparse adversarial perturbations on videos},
  author={Heo, Hwan and Ko, Dohwan and Lee, Jaewon and Hong, Youngjoon and Kim, Hyunwoo J},
  journal={IEEE Access},
  year={2021}
}Preprints
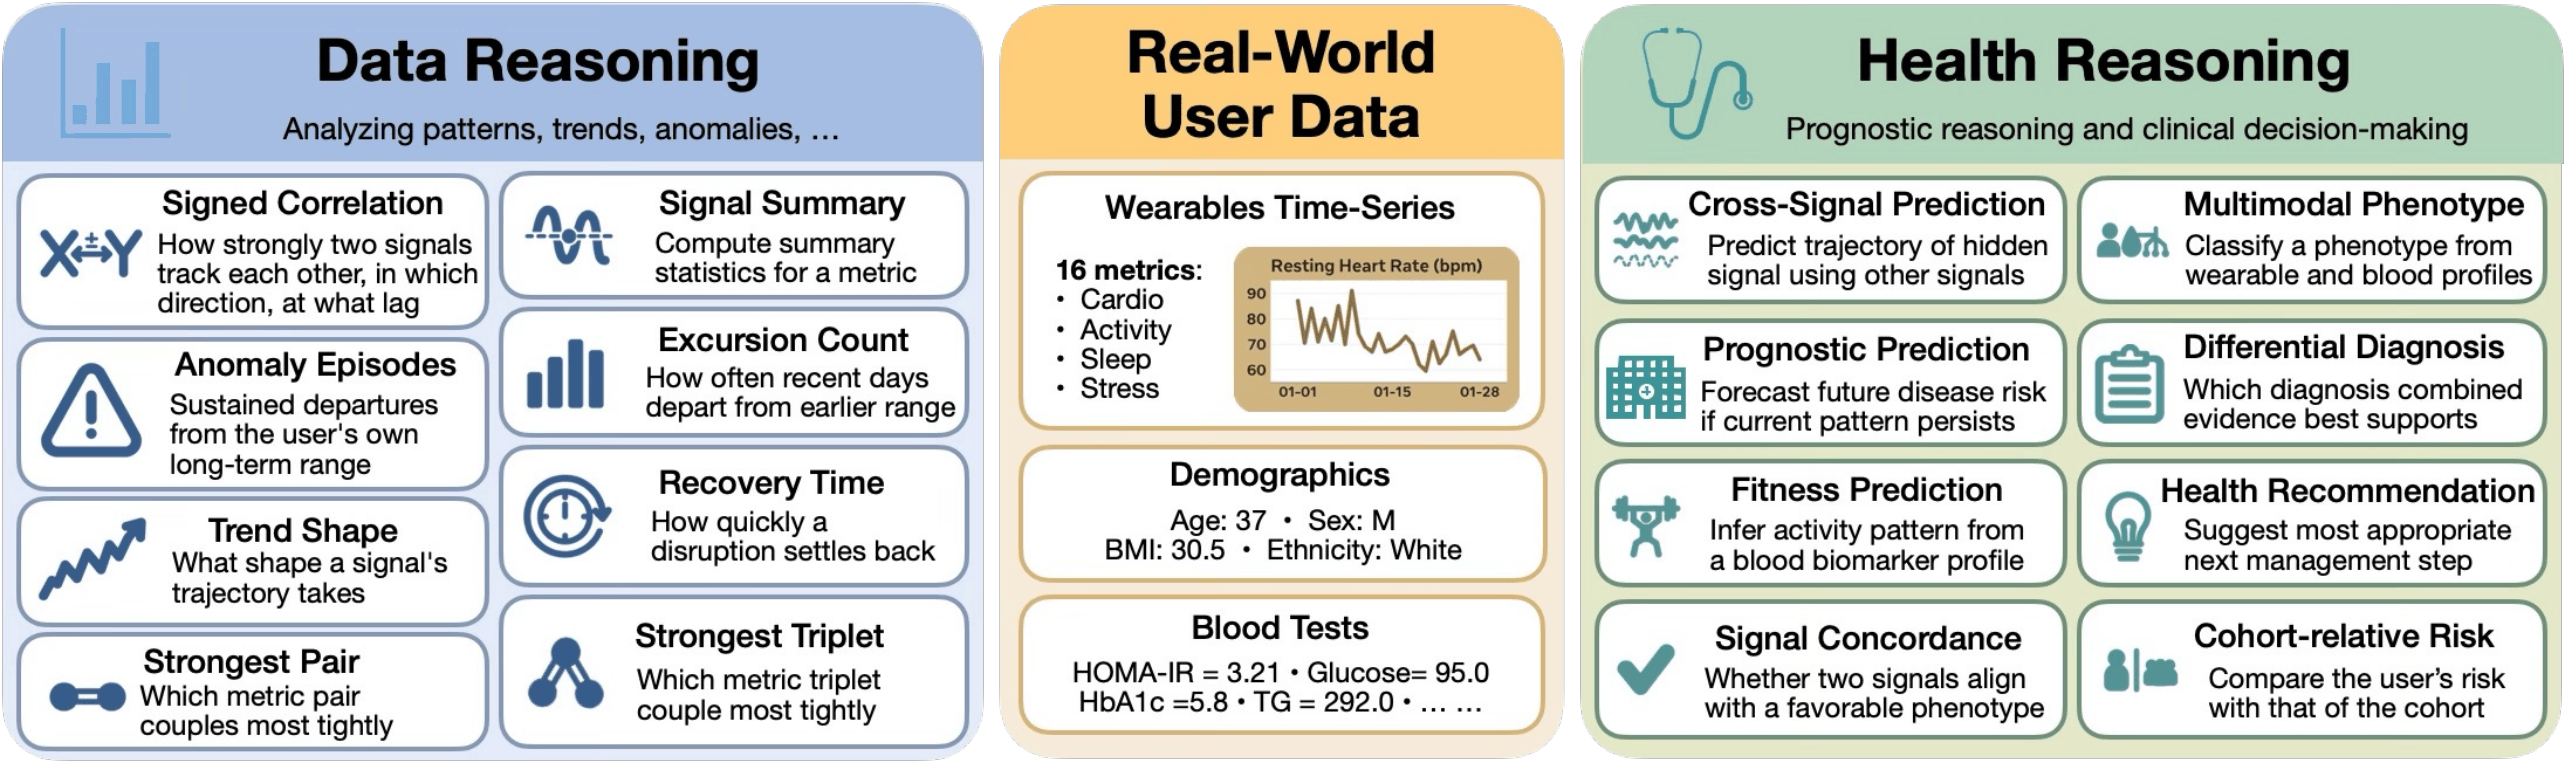
WearableQA: A Benchmark for Health Reasoning over Real-World Wearable Data
arXiv preprint 2026
@article{lee2026wearableqa,
  title={WearableQA: A Benchmark for Health Reasoning over Real-World Wearable Data},
  author={Lee, Ji Soo and Chen, Xilun and Chuang, Pierce and Shenoy, Ashish and Wei, Jason and Ko, Dohwan and Kim, Hyunwoo J. and Corda, Benoit},
  journal={arXiv preprint arXiv:2609.05405},
  year={2026}
}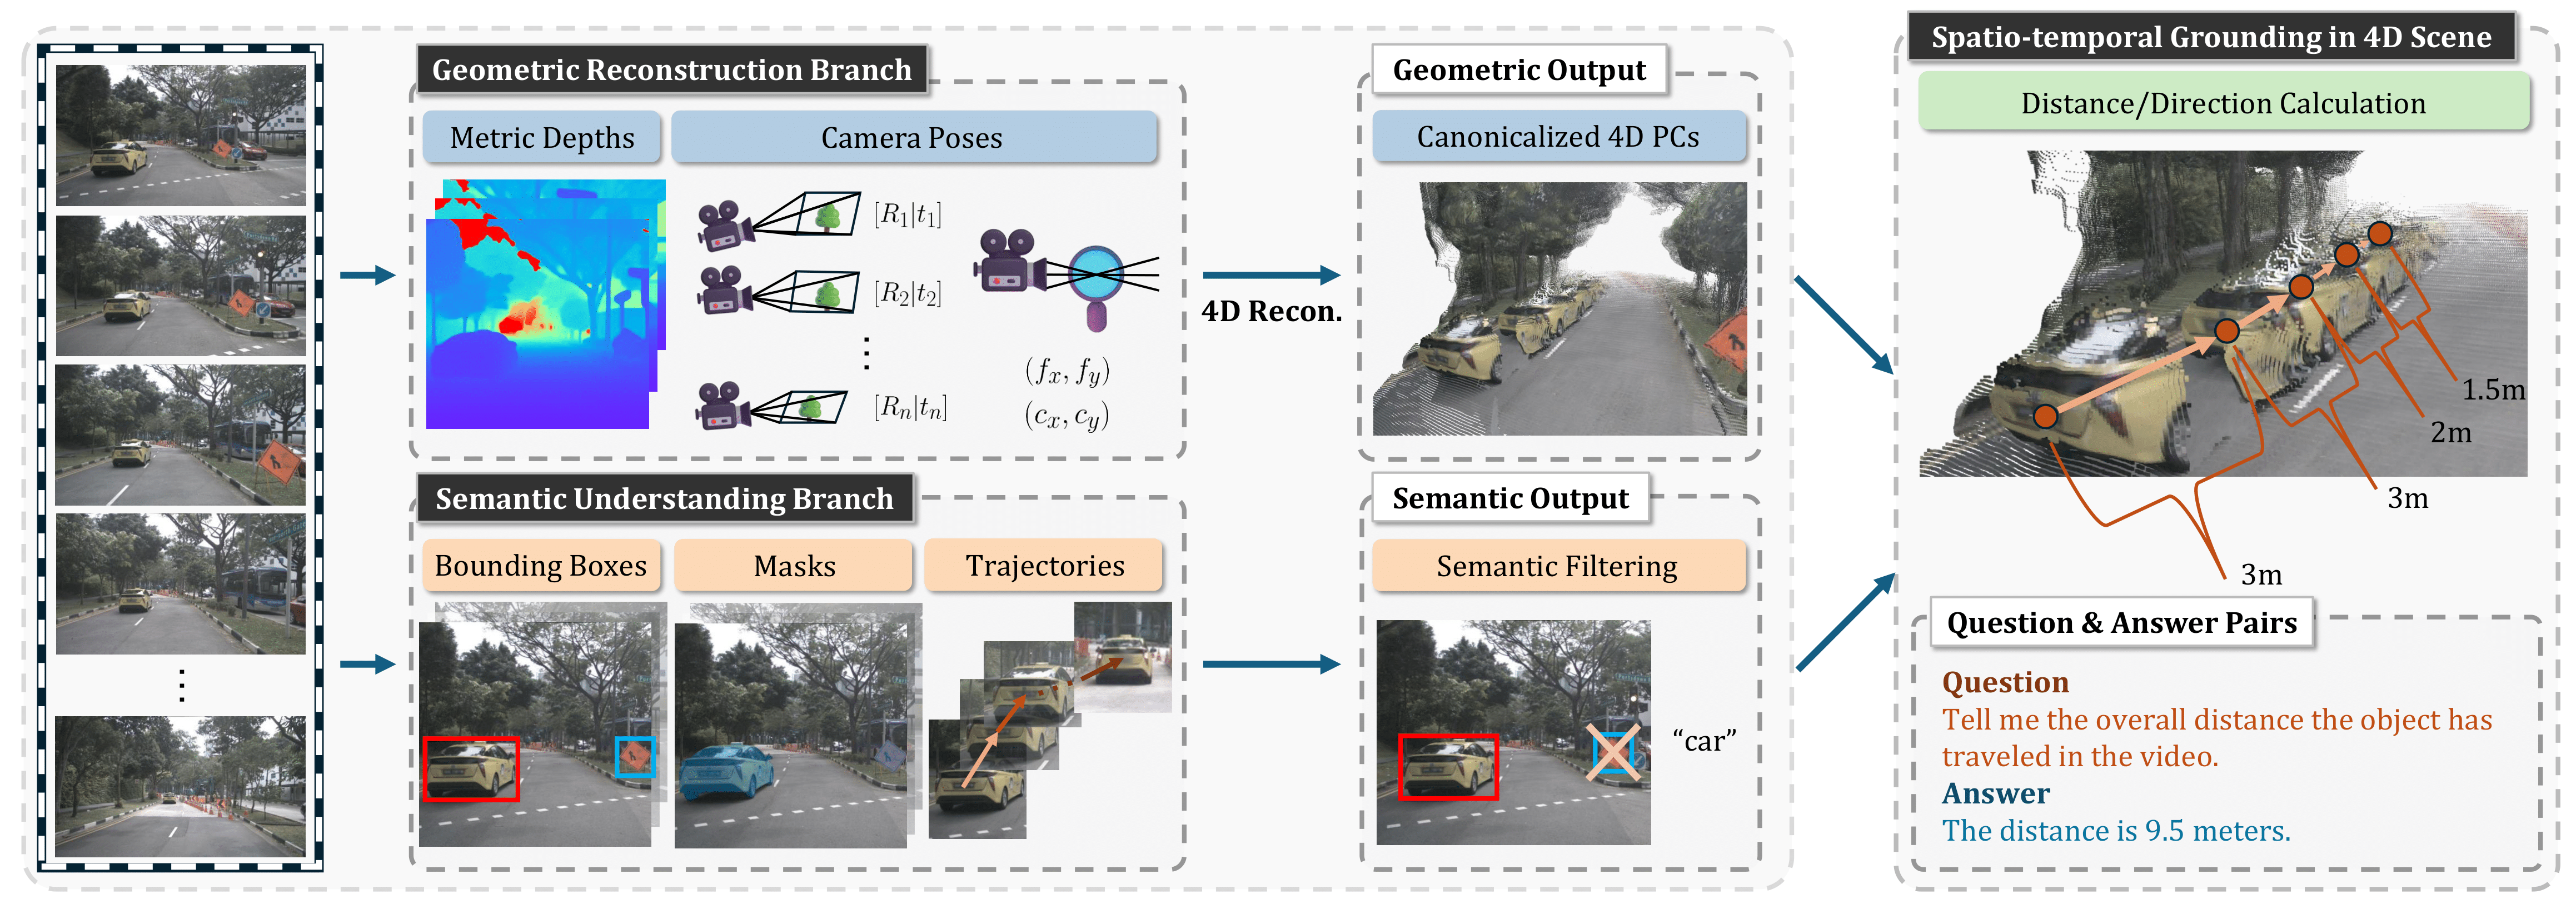
ST-VLM: Kinematic Instruction Tuning for Spatio-Temporal Reasoning in Vision-Language Models
arXiv preprint 2025
@article{ko2025st,
  title={St-vlm: Kinematic instruction tuning for spatio-temporal reasoning in vision-language models},
  author={Ko, Dohwan and Kim, Sihyeon and Suh, Yumin and Yoon, Minseo and Chandraker, Manmohan and Kim, Hyunwoo J and others},
  journal={arXiv preprint arXiv:2503.19355},
  year={2025}
}